I generally try to keep the Zvents posting light. This is not a long post about the company - it's just a quick note, somewhat of a milestone of awe. I've been so silent for so long because I've been utterly immersed, spun up in a tornado of business - for four months now, seemingly without end. It's been incredible. Exhausting. Exhilarating. I just did a quick count, and I've received 195 emails today - 97 of which came after 5pm. This past Memorial Day weekend, from 4pm on Friday through Monday at midnight, I personally did more business than many startups see in a month. At least six customer and partner calls, and endless email. This is not meant to brag. It's more of a sense of wonderment. When everything starts working, the net acceleration is just incredible.
I hope there's not a big wall out there just over the horizon, because we're moving at the speed of light.
Snapshot taken. We'll see in time which story it's telling.
Wednesday, May 28, 2008

Tuesday, April 15, 2008
AOL: The Network is the Content, the Network is the Ad
There are two big AOL announcements floating up TechMeme today. Most interesting is the news from Comscore that due to Platform A/Ad.com, AOL leads all major internet companies in reach, touching 9 out of 10 users on the internet.
The second is that AOL has acquired Sphere, Tony Conrad's blog recommendation engine, for about $25m. Since it launched three years ago, Sphere has done a great job of bringing its 'related commentary' widget to the content pages of very large sites like the New York Times, Washington Post, and Time magazine.
These two announcements are related, and I'm surprised that the usual commentators haven't picked up on this yet. The future of the internet is becoming increasingly clear -- it's advertorial, or a blend of commerce and content. In a huge number of cases, the content that users consume - presented either editorially, via search, or via a recommendation - is highly commercial in nature. If you care about gadgets, for instance, Engadget or Sony.com are both great landing sites for your online explorations. Cars? You may go to an enthusiast site, or Porsche.com.
Both content and advertising are best distributed via analytics- and algorithm-driven networks. Sphere is quite simply an algorithmic content redistribution network, and AOL's platform A is a (targeting) algorithm driven advertising network. These are different stripes on the same zebra.
Google, of course, has been experimenting with embedding content such as YouTube videos into its huge AdSense network; and there are a number of very interesting large-scale advertorial networks emerging such as Aggregate Knowledge's Pique. (Disclosure: I am an investor in AK). I will be very interested to see how AOL adds Sphere in to its market-leading network, and to watch how this emergent trend evolves.
Monday, March 17, 2008
Alan Greenspan is the Robert McNamara of economics
I was reading Krugman's latest piece on the ongoing meltdown of the capital markets, and he offered this quote:
It hit me: Greenspan, in practice and in retrospect, reminds me of nothing so much as Vietnam-era defense secretary Robert McNamara, the proponent of "the domino theory," and his still-ongoing and increasingly tragic efforts to shift all blame from himself long after the disastrous damage is done.

Greenspan's trumpeting of the ludicrous notion of efficient markets and support for the demise of market regulation will one day been recognized as equivalent folly.
The real tragedy here is that both of these men are geniuses in every sense of the word. It's impossible to watch The Fog of War and not come away impressed with McNamara. I highly recommend that film to anyone who has ever suffered even a little from hubris or ego. McNamara is smarter than you, better educated than you, more subtle and strategic than you, and he still blew it about as badly as a human being in power ever has done. Why? I can only guess, ideology.
Which is exactly how Greenspan has sent our country into our current tailspin.
Coming to a theater near you in 2028, _The Fog of Commerce_.
Hopefully, coming soon to a government near you, competence unblinded by nonsense.
Meanwhile, false beliefs in the political arena — the belief of Alan Greenspan and his friends in the Bush administration that the market is always right and regulation always a bad thing — led Washington to ignore the warning signs. By the way, Mr. Greenspan is still at it: accepting no blame, he continues to insist that “market flexibility and open competition” are the “most reliable safeguards against cumulative economic failure.”
It hit me: Greenspan, in practice and in retrospect, reminds me of nothing so much as Vietnam-era defense secretary Robert McNamara, the proponent of "the domino theory," and his still-ongoing and increasingly tragic efforts to shift all blame from himself long after the disastrous damage is done.
Greenspan's trumpeting of the ludicrous notion of efficient markets and support for the demise of market regulation will one day been recognized as equivalent folly.
The real tragedy here is that both of these men are geniuses in every sense of the word. It's impossible to watch The Fog of War and not come away impressed with McNamara. I highly recommend that film to anyone who has ever suffered even a little from hubris or ego. McNamara is smarter than you, better educated than you, more subtle and strategic than you, and he still blew it about as badly as a human being in power ever has done. Why? I can only guess, ideology.
Which is exactly how Greenspan has sent our country into our current tailspin.
Coming to a theater near you in 2028, _The Fog of Commerce_.
Hopefully, coming soon to a government near you, competence unblinded by nonsense.
Monday, March 10, 2008
NYTimes: It's all about the data, dummy!
Great article in the NYTimes on ad targeting and data scale. This is probably the first intelligent article in the mainstream media that I can remember on this topic - explaining that the combination of on-site and off-site behavioral data by consumers is what's driving the Internet today. An extension to the claims in this piece is that the same data is used to drive *products* (i.e. search relevance) as well as ad targeting; but I'll wait for their follow-up piece to close that gap.
Worth noting: The NYTimes has integrated "blogs" and their conversational style allows Louise Story to add some useful and interesting information to the more formal article. Check out her piece at the "Bits" blog for more data and further insight.
Some key quotes:
Data is the new lock-in and sustainable competitive advantage.
So how do you collect, store, and analyze all that data? That's why we built Hypertable...
Worth noting: The NYTimes has integrated "blogs" and their conversational style allows Louise Story to add some useful and interesting information to the more formal article. Check out her piece at the "Bits" blog for more data and further insight.
Some key quotes:
The rich troves of data at the fingertips of the biggest Internet companies are also creating a new kind of digital divide within the industry. Traditional media companies, which collect far less data about visitors to their sites, are increasingly at a disadvantage when they compete for ad dollars.I am pretty confident that there is at least one zero missing from every number the Times quotes in this article. This is happening today at a monumental scale, and will only get larger as time goes on.
The major television networks and magazine and newspaper companies “aren’t even in the same league,” said Linda Abraham, an executive vice president at comScore. “They can’t really play in this sandbox.”...
Web companies once could monitor the actions of consumers only on their own sites. But over the last couple of years, the Internet giants have spread their reach by acting as intermediaries that place ads on thousands of Web sites, and now can follow people’s activities on far more sites...
“So many of the deals are really about data,” said David Verklin...
Some advertising executives say media companies will have little choice but to outsource their ad sales to companies like Microsoft and Yahoo to benefit from their data. The Web companies may prove they can use their algorithms and consumer information to better select which ads for visitors better than media companies can.
“I think a lot of publishers are going to find they don’t have enough data,” said David W. Kenny, chief executive of Digitas, a digital advertising agency in the Publicis Groupe. “There’s only going to be a handful of big players who can manage the data.”...
Even with all the data Web companies have, they are finding ways to obtain more. The giant Internet portals have been buying ad-delivery companies like DoubleClick and Atlas, which have stockpiles of information. Atlas, for example, delivers 6 billion ads every day. The comScore figures do not capture such data.
Data is the new lock-in and sustainable competitive advantage.
So how do you collect, store, and analyze all that data? That's why we built Hypertable...
Monday, March 03, 2008
Google uses prior searches and spelling correction to match AdWords
I imagine that one of the problems that Google has is matching existing ad inventory against all the wonderful random crap that searchers type in - with many searches being really hard to monetize by "traditional" means. Thus the many experiments they run. I wonder what the ROI on this particular example is?
This is a random discovery which came about as I was looking up some old co-workers. First names have been changed to protect the innocent.
First I searched for my old co-worker "Ed" Biasi:

Note that there are no ads. Name searches are tough to monetize.
Then I searched for my old co-worker "Joe" Satchel:

Note the ad match - It's for a Biasia satchel - which is apparently some sort of $200 name-brand purse:

Not only is Google doing spelling correction on my Biasi search, they're remembering the immediate prior search term to match the ad. Apparently they only remember one prior search - when I did the same search twice (either Biasi or Satchel) the ad disappeared.
Fascinating.
This is a random discovery which came about as I was looking up some old co-workers. First names have been changed to protect the innocent.
First I searched for my old co-worker "Ed" Biasi:
Note that there are no ads. Name searches are tough to monetize.
Then I searched for my old co-worker "Joe" Satchel:
Note the ad match - It's for a Biasia satchel - which is apparently some sort of $200 name-brand purse:
Not only is Google doing spelling correction on my Biasi search, they're remembering the immediate prior search term to match the ad. Apparently they only remember one prior search - when I did the same search twice (either Biasi or Satchel) the ad disappeared.
Fascinating.
Tuesday, February 19, 2008
Hypertable - press and traction
It's now been two weeks since we launched the 0.9 alpha of the Hypertable distributed database, and we've been a bit blown away with the excitement it's generated. The release got picked up on Slashdot (w00t!), in LinuxWorld, and just today, the 451 Group in the UK published another great piece. Meanwhile it's causing a little enthusiastic consternation in relational land -- my absolute favorite quote is from DBA4Life:
Most exciting, however is the level of engagment we've seen with the actual codebase, since that's where real open-source traction occurs. In addition to a vibrant mailing list, we're getting tons of feedback and bug reports - perhaps driven by the fact that in just two weeks, Hypertable has seen over 2600 downloads (!) -- of a 700MB tarball that you need significant skills to unpack and install. We're seeing all sorts of cool ideas about how this could be used, and look forward to many more.
Meanwhile, Zvents is laser-focused as always on the future of local search...
"HyperTable is sexy... yet, not relational... This is very confusing... I have to go now."That's the sound of the world changing :-)
Most exciting, however is the level of engagment we've seen with the actual codebase, since that's where real open-source traction occurs. In addition to a vibrant mailing list, we're getting tons of feedback and bug reports - perhaps driven by the fact that in just two weeks, Hypertable has seen over 2600 downloads (!) -- of a 700MB tarball that you need significant skills to unpack and install. We're seeing all sorts of cool ideas about how this could be used, and look forward to many more.
Meanwhile, Zvents is laser-focused as always on the future of local search...
Tuesday, February 05, 2008
Hypertable is launched!
For the past year, Zvents has been sponsoring the open-source Hypertable project for a distributed, web-scale database and analytics platform. I am *very* pleased to announce that earlier today, the alpha version of Hypertable became available for download, at the new hypertable.org site.

Data scaling dudes of the world, rejoice!
Data scaling dudes of the world, rejoice!
Thursday, January 31, 2008
AbleGrape: Superb new vertical search engine for wine
I love this story. It's what Web 2.0 is *supposed* to be about, but rarely is.
Here are some of the key themes of Web 2.0:
* Search is centric
* Open-source software makes starting up cheap
* People who lived and learned from Web 1.0 applying the lessons to succeed
* Increased internet usage makes niche sites possible and profitable
* New UI tools (AJAX etc.) make UI innovation possible again
So what do we actually get? A few great new companies, and a bunch of silly no-hope websites trying to make money off of each other's widgets. Uncov, we miss you already.
That's why I love AbleGrape, which my friend Doug Cook just launched earlier this week. AbleGrape is a vertical search engine for wine:

At launch, it supports English, French, and Italian; it has fully international content; it has really interesting new UI features for fast, sophisticated searching; and it's astonishingly relevant for even obscure wine queries.

The release email states:
He has spent the past 2 1/2 years building AbleGrape himself from the ground up - coding, tuning the crawl and relevance, and engaging with the thousands of vineyards, negociants, appellation boards, government agencies, and other businesses and entities that make up the wine world. This has been a huge solo effort -- a personal memory I have of the process is watching Doug attempt to check the status of his crawl over a 9800 baud dial-up connection from a house in the Tuscan countryside of Italy - in August, 2006.
Let's walk through that supposed Web 2.0 stack again:
* Search is centric
--> AbleGrape a search engine. A damn fine one.
* Open-source software makes starting up cheap
--> Doug built AbleGrale with major pieces from the Lucene/SOLR/Nutch open source projects
* People who lived and learned from Web 1.0 applying the lessons to succeed
--> Inktomi to Yahoo to AbleGrape. Check!
* Increased internet usage makes niche sites possible and profitable
--> Let's hope -- for every wine question that you have, this is the first place you should go.
* New UI tools (AJAX etc.) make UI innovation possible again
--> Doug has a number of fast, clever, interactive features for search refinement based on his years of search experience that take a second to learn, but are really useful. Doug describes them better than I would.
Amidst all the baloney, hype, and general mediocrity of much of the Internet space, examples like this give me hope and happiness. This rocks. Great job, Doug!
Sadly, I have no financial interest in this company. But Doug does share superb wine with me from time to time.
Here are some of the key themes of Web 2.0:
* Search is centric
* Open-source software makes starting up cheap
* People who lived and learned from Web 1.0 applying the lessons to succeed
* Increased internet usage makes niche sites possible and profitable
* New UI tools (AJAX etc.) make UI innovation possible again
So what do we actually get? A few great new companies, and a bunch of silly no-hope websites trying to make money off of each other's widgets. Uncov, we miss you already.
That's why I love AbleGrape, which my friend Doug Cook just launched earlier this week. AbleGrape is a vertical search engine for wine:
At launch, it supports English, French, and Italian; it has fully international content; it has really interesting new UI features for fast, sophisticated searching; and it's astonishingly relevant for even obscure wine queries.
The release email states:
We aim to be your first online stop for trustworthy, up-to-date wine information. Our public beta covers some 32,000 wine sites, with about 10 million pages of content, and we've put a lot of work into returning highly relevant results and providing an innovative, powerful user interface that helps you find things faster.Doug Cook, the founder, coder, sole proprietor, and general polymath behind this achievement, was formerly a search engineer at Inktomi, and rose to VP of Engineeringat Yahoo! Search after the acquisition. He's also a world-class wine guy, who speaks several wine-useful languages fluently and has one of the better wine collections I've ever seen.
He has spent the past 2 1/2 years building AbleGrape himself from the ground up - coding, tuning the crawl and relevance, and engaging with the thousands of vineyards, negociants, appellation boards, government agencies, and other businesses and entities that make up the wine world. This has been a huge solo effort -- a personal memory I have of the process is watching Doug attempt to check the status of his crawl over a 9800 baud dial-up connection from a house in the Tuscan countryside of Italy - in August, 2006.
Let's walk through that supposed Web 2.0 stack again:
* Search is centric
--> AbleGrape a search engine. A damn fine one.
* Open-source software makes starting up cheap
--> Doug built AbleGrale with major pieces from the Lucene/SOLR/Nutch open source projects
* People who lived and learned from Web 1.0 applying the lessons to succeed
--> Inktomi to Yahoo to AbleGrape. Check!
* Increased internet usage makes niche sites possible and profitable
--> Let's hope -- for every wine question that you have, this is the first place you should go.
* New UI tools (AJAX etc.) make UI innovation possible again
--> Doug has a number of fast, clever, interactive features for search refinement based on his years of search experience that take a second to learn, but are really useful. Doug describes them better than I would.
Amidst all the baloney, hype, and general mediocrity of much of the Internet space, examples like this give me hope and happiness. This rocks. Great job, Doug!
Sadly, I have no financial interest in this company. But Doug does share superb wine with me from time to time.
TubeMogul's sweet new video distribution and analytics service launches at DEMO
Video distribution on the Internet is already a huge and fragmented market, with consumer traction spread across a host of destination sites and widgets from VideoEgg to Vimeo to YouTube. It's also a rapidly growing and evolving market, with potential big players like Hulu lurking in the wings.
So if you've got video to distribute, and understanding consumer uptake is the lifeblood of your business, what do you do?
One great answer is TubeMogul, which formally launched its distribution and analytics service at DEMO yesterday. I am proud to be an investor in TubeMogul via my partnership at NetService Ventures.

TubeMogul has a great product that's gotten significant initial traction, both with major users like CBS Interactive and with a long tail of more than ten thousand video creators. Their launch saw some great press commentary as well. Hats off to Brett and the team for a great job thus far!
I think that TubeMogul, as well as another NSV investment, SingleFeed, are representative of an emergent trend toward distinct buyer- and seller- focused analytic offerings as multiple Internet marketplaces evolve from their initial stages toward a more sophisticated bid/ask framework. I'll have a further post on that soon.
So if you've got video to distribute, and understanding consumer uptake is the lifeblood of your business, what do you do?
One great answer is TubeMogul, which formally launched its distribution and analytics service at DEMO yesterday. I am proud to be an investor in TubeMogul via my partnership at NetService Ventures.
TubeMogul has a great product that's gotten significant initial traction, both with major users like CBS Interactive and with a long tail of more than ten thousand video creators. Their launch saw some great press commentary as well. Hats off to Brett and the team for a great job thus far!
I think that TubeMogul, as well as another NSV investment, SingleFeed, are representative of an emergent trend toward distinct buyer- and seller- focused analytic offerings as multiple Internet marketplaces evolve from their initial stages toward a more sophisticated bid/ask framework. I'll have a further post on that soon.
Tuesday, January 29, 2008
Google Newspaper Ads 2008 = CueCat 1998
Congratulations, Google. You've managed to revive one of the dumbest and most reviled companies of Web 1.0 Your new newspaper ad bar code plan smacks of nothing so much as CueCat, the ill-fated money pit that Forbes, Radio Shack, and others poured tens of foolish millions into. People really hated the CueCat.

Good luck with that.
Update: Commentary on this is breaking out into two distinct camps: Those who were grownups during Web 1.0 and paid attention, and those who were either younger than 12, or missed what went wrong.
I'm proud to be with the grumpy oldsters here, and Joel nails it with "it doesn't say much for the quality of those 150 people Google hires every week that they're now chasing some of the worst of the bad ideas of the fin de siecle."
Monday, January 28, 2008
Zvents launches federated local search
I try to keep the Zvents product announcements to a minimum, but I'm really excited about this one. As part of our ongoing expansion of focus on local search, we've launched a new federated local search page on Zvents.com. We've been live with dozens (now hundreds) of media partners for over 18 months, and we've observed behavior of both searchers and local merchants that strongly suggested that we should unify our search experience across events, venues, restaurants, and performers. As we add in additional categories of local merchants, this blended result becomes even more important.

Doing federated search well is a hard, open problem, and while I don't think we have the perfect answer yet, this is a huge step forward for us, and an indicator of many great things to come. I'm loving our role as the deep technology provider for local media, and looking forward to more cool things we'll be rolling out in 2008.
There are a couple of nice writeups from Chris Smith at the Natural Search Blog and Greg Sterling at Screenwerk.
Check it out!
Saturday, January 19, 2008
Dear Hippies: Your cool car is starving poor people
I've always thought that biodiesel was a dumb idea. Maybe it's because I grew up on a farm in Ohio, where a yield of 180 bushels of corn to an acre of land is considered outstanding, on some of the richest farm land in the world, where water falls from the sky. 180 bushels of corn may sound like a lot (a bushel is about 9 gallons for you city types) but this site says you get a grand total of 2.7 gallons of ethanol from a bushel. At 25 miles per gallon, that will drive one car about 12,000 miles -- the average distance that most people drive in a year.
This other site (thanks, Google!) says that you get 134,000 food calories from that same bushel - which is enough to feed a person for 61 days.
So that's your tradeoff -- from a single acre of good farm land, enough food to feed 30 people for a year, or enough ethanol to support one single car, driven as we do today, for a year. 30 people vs. one car. Huh.
It is just about now, dear reader, that it should be dawning on you that the oil economy only works because the entire biomass of millions of years worth of extremely energy-rich plants and animals were compressed into this super-handy stuff we called oil. We have busily extracted this incredibly concentrated goodness from every convenient and many inconvenient places on earth, to the point where its future supply grows uncertain; and we frac it down into the gasoline we put into our cars, and kid ourselves that cleverness and progress is the root cause of our luxurious lifestyles, rather than the tapping of this one-time bonus from the geophysical history of the earth.
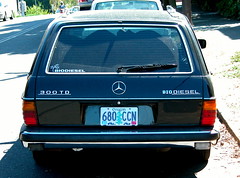
From Flickr: Originally uploaded by Michiel2005
And now, as the remaining loose change from that historic bonus starts to rattle around in our pocket, we're desperately casting around for alternatives - and wondering if the globe's yearly spread-out dose of agricultural sunshine can somehow support a lifestyle grown large and fat on the hyper-concentrated fossil extract, without negative consequence.
Um, no.
But don't just take my word for it. Bitter economic truth is exerting itself as we speak, as demand for biofuels grows due to a combination of dopey hippies, foolish politicians, and farmers who never saw a subsidy they didn't like -- I'm looking at you, Iowa-caucus-goers and your bizarre cartel to mis-direct the agenda of U.S. presidential politics. Here's a great article in the New York Times that lays out how globally,poor people are either paying more money for oils or eating less calories because of this trend.
I am a big fan of environmentalism, but at its core enviromentalism means that we must do more with less. Many big green trends today - can you say "carbon credits" for your sports car -- are attempts to deny reality and kid ourselves about the innovation or sacrifices that are yet required of us. Biodiesel is yet another of those false, self-indulgent dead ends.
But there's hope. "The do more" part of the honest environmental equations fires me up. One reason I love the business of computers and communication is that it drives incredible efficiencies in the physical world. I am wildly excited about the many opportunities for innovation - which is what drives TRUE progress - but in order to concentrate on what matters, we have to stop pretending that dumb farm subsidies can save us, and get to work.
This other site (thanks, Google!) says that you get 134,000 food calories from that same bushel - which is enough to feed a person for 61 days.
So that's your tradeoff -- from a single acre of good farm land, enough food to feed 30 people for a year, or enough ethanol to support one single car, driven as we do today, for a year. 30 people vs. one car. Huh.
It is just about now, dear reader, that it should be dawning on you that the oil economy only works because the entire biomass of millions of years worth of extremely energy-rich plants and animals were compressed into this super-handy stuff we called oil. We have busily extracted this incredibly concentrated goodness from every convenient and many inconvenient places on earth, to the point where its future supply grows uncertain; and we frac it down into the gasoline we put into our cars, and kid ourselves that cleverness and progress is the root cause of our luxurious lifestyles, rather than the tapping of this one-time bonus from the geophysical history of the earth.
From Flickr: Originally uploaded by Michiel2005
And now, as the remaining loose change from that historic bonus starts to rattle around in our pocket, we're desperately casting around for alternatives - and wondering if the globe's yearly spread-out dose of agricultural sunshine can somehow support a lifestyle grown large and fat on the hyper-concentrated fossil extract, without negative consequence.
Um, no.
But don't just take my word for it. Bitter economic truth is exerting itself as we speak, as demand for biofuels grows due to a combination of dopey hippies, foolish politicians, and farmers who never saw a subsidy they didn't like -- I'm looking at you, Iowa-caucus-goers and your bizarre cartel to mis-direct the agenda of U.S. presidential politics. Here's a great article in the New York Times that lays out how globally,poor people are either paying more money for oils or eating less calories because of this trend.
I am a big fan of environmentalism, but at its core enviromentalism means that we must do more with less. Many big green trends today - can you say "carbon credits" for your sports car -- are attempts to deny reality and kid ourselves about the innovation or sacrifices that are yet required of us. Biodiesel is yet another of those false, self-indulgent dead ends.
But there's hope. "The do more" part of the honest environmental equations fires me up. One reason I love the business of computers and communication is that it drives incredible efficiencies in the physical world. I am wildly excited about the many opportunities for innovation - which is what drives TRUE progress - but in order to concentrate on what matters, we have to stop pretending that dumb farm subsidies can save us, and get to work.
Friday, January 04, 2008
Rich Democracts vs. Poor Republicans
The results of the Iowa caucuses presage the coming big shift in American electoral politics. The Democrats are going to become the party of money and modernity, and the Republicans are going to become the party of economic populism and social conservatism. Some interesting results:
* Mike Huckabee (economic populist, social conservative) won the Republican vote.
* John Edwards (economic populist) won the self-described conservative vote caucusing Democratic.
* Mitt Romney (A Democrat in spirit - the Bain Capital governor of Massachusetts) lost the Republican race big to Huckabee.
Obama is a candidate that can deliver the White House to the Democrats in a transitional phase from 2008 to 2016 -- in part because he will hold the votes of African-Americans, who otherwise favor both economic populism and social conservatism. Look for a Republican to win a surprising victory around 2020 in part by winning black votes, and look for increasing rejection of President Obama as "not a real black man" by the end of his second term.
Meanwhile, the Democrats become the party of business and trade. John Edwards may run for president again, but he'll do so as a Republican -- and the unions (the few that are left) will back him again, and vote a Republican ticket.
The Hispanic vote will become the new Democratic flank, replacing blacks - since "economic populism" will include anti-immigrant and anti-Spanish-speaking sentiment, expressed by both blacks and whites.
You may now return to your regularly scheduled technology.
Thursday, January 03, 2008
Calculated Risk: Great finance analysis, great writing
Or, Uncov for the mortgage industry ;-)
Silicon Valley is as much about finance as it is about technology, and I appreciate great finance writing as much as I love great technology analysis. Silicon Valley is also a real-estate-obsessed place, so when that finance writing is about the greatest financial calamity to ever beset the housing market, the enjoyment is multiplied.
I'd like to call out Calculated Risk, a superb blog on the mortgage and housing industry, with two pseudonymous authors (CR and Tanta) who write with enormous knowledge and great flair about the debacle in progress on Wall Street and in Middle America right now.
In particular the recent post, "The Un-re-dis-inter-mediation Blues," is a scathing indictment of the sort of business model foolishness -- in this case carried out by Merrill Lynch -- that you may have thought was only the province of Web 2.0 startups. Highly recommended, and a good mental tonic when too many thoughts of advertising-supported business models and viral marketing are getting you down:
Aside from the idea of loan officers having sufficient spelling skills to play Scrabble, which is new to me, here we have the two same old dumb ideas that emerge in any mortgage downturn, with a delicious twist that it's Wall Street getting it instead of Main Street.
First, there's the old "let's retrain a bunch of subprime loan officers to be prime GSE loan officers." You civilians might think this should be fairly easy, but the fact is that training a lot of these people to be prime loan officers basically means training them to be loan officers. If they had any basic depth of understanding of the business they're in, they could move to prime origination by just reading that other rate sheet. The reality is that they've been doing no-doc no-down no-sweat stuff for so long--some of them have never done anything but--that they're sitting around with the PlayStation waiting for someone to tell them how a 30-year fixed rate loan with a down payment and verified income actually works...
Item the second causes a deep belly laugh in anyone who ever worked for a depository in a mortgage downcycle: "Why can't we just put the loans on the balance sheet?" I know it makes me a bad person, but the thought of Merrill getting this one from its mortgage people is floating me heavenward on a warm tide of schadenfreude...
That is--or once was--an old strategy for depositories: when you can't sell your loans, hunker down, stuff 'em on the books and wait for the tide to turn. We are seeing depository after depository shutting down its wholesale and correspondent lending divisions, meaning it will, as always, only allocate those portfolio dollars to keeping an expensive but much safer retail operation alive...
But Merrill really really wanted to be a retail originator in its own right. Welcome to the other side of the mortgage world, Mother Merrill, and try turning in some tiles. Maybe you'll get a vowel.
Thursday, December 06, 2007
The power of traditional media: NPR and Kipling
I've gotten several phone calls from friends who heard my comment read on NPR's All Things Considered this evening. I was upset with their Tuesday story on a new Rudyard Kipling museum in Mumbai, and dashed off an email to the comment form on their site.
A few observations:
* I write on this blog at least weekly, and rarely hear from friends about its contents. The reach of traditional media and its broadcast/push format still have incredible power to communicate and persuade.
* I can write whatever I want on this blog, and yet I'm thrilled to get 30 seconds of airtime, edited and second-hand, on NPR. I can't quite express why that is; perhaps because it feels like I've passed some test.
* "Passing a test" is a very useful metric for writing. I actually crafted my comment carefully to be succinct and punchy, knowing that if I rambled I wouldn't get air time. Editors may sometimes be wrong, but they're direct; whereas if your audience doesn't like what or how you write, they just go away, typically without telling you.
* Don't offer up shallow interpretations of Kipling when I'm around, unless you've read a lot more of him and about him than I have, and are rhetorically fast on your feet.
Tuesday, December 04, 2007
Giga, Tera, Peta: Om on Google's Infrastructure
Om writes that Google's infrastructure is its strategic advantage. He lists "fiber networks, data centers, switches, servers and storage devices" as key components. He correctly identifies "Relevancy of results, Speed of search, and Cost of executing a search query" as key benefits of this infrastructure.
All true (and better ad targeting is a fourth key benefit).
My only beef: Where's the software?
A huge portion of Google's opex is people, and many of those people are the systems guys who built fundamental software infrastructure like UNIX, C, and TCP/IP. Those guys aren't there for their halo effect - they're there, despite Google's youth bias, to build software infrastructure.
Scan this Bell Labs alumni list, and see how many times Google comes up as a current gig. Answer: 21.
As Steve Jobs continues to demonstrate in the consumer device sphere, custom hardware + genius software yields magic. Google is the server-side doppelganger to Apple, and their platforms like GFS, BigTable, MapReduce, and Sawzall are core to their competitive advantage. For a great overview of how software and hardware work together at Google, check out this great 2006 presentation on Google internals by Toby DiPasquale.
Zvents also believes in great software infrastructure. More soon on that front.
Update: If you're showing up from TechMeme and you find this post interesting, there are plenty more on related topics. It's been a bit rich about Google here on the blog lately, but they are the dominant technological force of our times. Just click here and hit page down.
Sunday, December 02, 2007
What Google hates and loves: Why Wikipedia is taking over search results
John Battelle recently posted a report which states that Wikipedia pages are taking over the organic search results of the major search engines: "Today 27% of Google’s results on the first link alone come from Wikipedia, as do 31% of Yahoo’s."
What magic power causes a free site like Wikipedia to own between a quarter and a third of results for the single most powerful page position at the world's two largest search engines?
It's simple. Money.
Google and Yahoo make more money by putting Wikipedia and sites like it first in their results.
Let's look at a scenario that Google hates. Christmas is coming, and a searcher puts a broad but valuable query term like HDTV into Google. The results that come back are clearly delineated between organic content and paid ads:

But here's what drives Google (and Yahoo) absolutely crazy. There in the third link position is CNET, with a feature called HDTV World. CNET is a media company which creates great, rich content about tech topics like HTDV. Google can hardly ignore them. But boy, do they wish they could! Because in two short clicks, a user goes from the organic results on Google to a highly monetized buying guide and store for Samsung HDTVs on CNET -- and Google makes exactly $0.

It's enough to cause heartburn at the 'plex.
Now let's walk through that scenario with a similar search for hearing aids. In passing, it's interesting to note that Google has no top-line ads for 'HDTV' (which I presume young, savvy people search for) and it displays three top-line ads for 'hearing aid' - which I presume older, less savvy searchers tend to type in. Nothing to see here, they're still not evil, just as long as they keep it below 49%.
Ahem. Back to our topic at hand, Wikipedia love.
Here's the paid/unpaid split for hearing aids:

We can see that like the HDTV search, Wikipedia is the first organic result, which means that it will collect the bulk of the clicks for unpaid traffic on the page. This delights Google, because there are no ads on Wikipedia. By displaying Wikipedia links in the most prominent free position, not only can they deliver a useful result to a searcher, they can't get into the CNET/HDTV situation which they hate - letting a searcher with strong commercial intent escape without the lucky advertiser paying the Google tax.
There's a further benefit to Google in promoting Wikipedia in organic results. Even within the context of a buying decision, searchers strongly type for commercial and non-commercial intent of a particular query. When a searcher is in the exploration and research phase of a hearing-aid buying decision, they want information, overview, context. When they have found out what they want, they switch to a transactional mode, and are ready to be marketed to. Over time, Google can use free, non-commercial content like Wikipedia to actively train searchers that they won't find commercial offers in the organic results:

...and over time, encourage them to look first in the paid ad positions when they want to buy something. Commercial nirvana.

That commercial nirvana is why Google and Yahoo love Wikipedia, and you'll continue to see more Wikipedia links in high organic positions over time.
Unless Jimmy Wales allows ads.
Update: I've just noticed Matt Cutts' new post on Google's efforts to nuke people who sell links with PageRank. Matt asks, rather piously, "Now, think about how you would feel if your medical search was influenced by pages like this," and points to a paid content page about the Gamma Knife, which is apparently a cancer treatment.
Hmm, Matt, I'd feel about the same as I do when Google influences my search by prominently showing a Gamma Knife ad on the first SERP:

Let's be clear - piety aside, Google isn't worried about your finding out about the Gamma Knife - they just want someone to pay them. That's why they are happy to prominently feature it in their ads at the same time that Matt is finger-wagging about it in his blog.
This battle is all about searcher differentiation, and paying the Google Tax on the way to commercial nirvana.
Note: For more on query-type differentiation, see my previous post, "Why Google owns your lunch."
What magic power causes a free site like Wikipedia to own between a quarter and a third of results for the single most powerful page position at the world's two largest search engines?
It's simple. Money.
Google and Yahoo make more money by putting Wikipedia and sites like it first in their results.
Let's look at a scenario that Google hates. Christmas is coming, and a searcher puts a broad but valuable query term like HDTV into Google. The results that come back are clearly delineated between organic content and paid ads:
But here's what drives Google (and Yahoo) absolutely crazy. There in the third link position is CNET, with a feature called HDTV World. CNET is a media company which creates great, rich content about tech topics like HTDV. Google can hardly ignore them. But boy, do they wish they could! Because in two short clicks, a user goes from the organic results on Google to a highly monetized buying guide and store for Samsung HDTVs on CNET -- and Google makes exactly $0.
It's enough to cause heartburn at the 'plex.
Now let's walk through that scenario with a similar search for hearing aids. In passing, it's interesting to note that Google has no top-line ads for 'HDTV' (which I presume young, savvy people search for) and it displays three top-line ads for 'hearing aid' - which I presume older, less savvy searchers tend to type in. Nothing to see here, they're still not evil, just as long as they keep it below 49%.
Ahem. Back to our topic at hand, Wikipedia love.
Here's the paid/unpaid split for hearing aids:
We can see that like the HDTV search, Wikipedia is the first organic result, which means that it will collect the bulk of the clicks for unpaid traffic on the page. This delights Google, because there are no ads on Wikipedia. By displaying Wikipedia links in the most prominent free position, not only can they deliver a useful result to a searcher, they can't get into the CNET/HDTV situation which they hate - letting a searcher with strong commercial intent escape without the lucky advertiser paying the Google tax.
There's a further benefit to Google in promoting Wikipedia in organic results. Even within the context of a buying decision, searchers strongly type for commercial and non-commercial intent of a particular query. When a searcher is in the exploration and research phase of a hearing-aid buying decision, they want information, overview, context. When they have found out what they want, they switch to a transactional mode, and are ready to be marketed to. Over time, Google can use free, non-commercial content like Wikipedia to actively train searchers that they won't find commercial offers in the organic results:
...and over time, encourage them to look first in the paid ad positions when they want to buy something. Commercial nirvana.
That commercial nirvana is why Google and Yahoo love Wikipedia, and you'll continue to see more Wikipedia links in high organic positions over time.
Unless Jimmy Wales allows ads.
Update: I've just noticed Matt Cutts' new post on Google's efforts to nuke people who sell links with PageRank. Matt asks, rather piously, "Now, think about how you would feel if your medical search was influenced by pages like this," and points to a paid content page about the Gamma Knife, which is apparently a cancer treatment.
Hmm, Matt, I'd feel about the same as I do when Google influences my search by prominently showing a Gamma Knife ad on the first SERP:
Let's be clear - piety aside, Google isn't worried about your finding out about the Gamma Knife - they just want someone to pay them. That's why they are happy to prominently feature it in their ads at the same time that Matt is finger-wagging about it in his blog.
This battle is all about searcher differentiation, and paying the Google Tax on the way to commercial nirvana.
Note: For more on query-type differentiation, see my previous post, "Why Google owns your lunch."
Tuesday, November 20, 2007
Why Google owns your lunch: The "I'm feeling lucky" button
Google is a force of nature in global business today, in the same way that the Velociraptors ate everything in Jurassic Park, and Napoleon conquered everything non-frozen in Europe.
So I am bemused at Valleywags's credulous acceptance of Sergey Brin's statement that the "I'm Feeling Lucky" button costs Google $100+ million a year because they miss out on the advertising on the subsidiary pages when users click that button.
Yeah, right. Aren't you Valleywag guys supposed to be snarky?
News flash, Silicon Valley: Google is composed of some of the smartest machine-learning dudes to ever walk the planet. They have transcended their humble beginnings in web graph analysis to meet their true calling, which is to capture and analyze every single bloody user click, everywhere, ever, that they can get their hands on.
Within that context, if you think that the "I'm feeling lucky" button still exists because of some avatistic non-commercial motive within Google, get a clue. While a friendly grad-student impulse may have been the original source of the button, that button has long since proven its worth on a simple, highly commercial scale: query term type differentiation.
There are, broadly, three classes of queries on the Internet: discovery/information, navigation, and transaction. "Navigation" is of the type: "I need to know the URL for IBM, please take me there." A considerable amount of query-response and relevance angst is expended by most search engines on differentiating the three types of user intent, because users in each mode have vastly different expectations. Google, unlike others, gets at least half of this differentiation for free, because of that magic, friendly, 'Lucky' button.
Sergey, that's worth $110 million and more, and you know it.
That crucial differentiation makes Google search better; and better = more profitable. Scoreboard!
How and why does this work?
Because there is a strong predominance of searchers with navigational intent who click the 'Lucky' button. Users with informational (discovery) or transactional intent, on the other hand, tend to click the 'search' button. That distinction allows Google to build a dictionary which correlates a certain set of search terms with likely navigational intent -- for free, in machine learning terms. Voila! Google take a set of searchers with inherent low monetization potential -- after all, they only wanted to find their way to IBM's website -- and makes its insanely profitable search engine even better.
money...
...money...
...money
Sergey may pitch this as some charitable instinct on Google's part, but we know better.
Rock On, Google Borg!
Footnote: I talk a good game, but I only vaguely understand this stuff, and I am thrilled and humbled on a daily basis by the brilliance of the people who work with me and help me understand how much this sort of science and engineering matters. Thanks, Z Team!
Monday, November 12, 2007
Waiting for Virgin America...
I tried three times to do a flight search on Virgin America.

No dice.
JetBlue just got over $1000 of my business, because their web site works.
Web sites matter, people. Site performance and search performance are two of the most critical customer-service metrics you can measure, across an incredibly wide range of retail and commercial endeavors. They're hard to do well. Which is why they matter even more than you think -- because you can differentiate from your competitors, and delight your customers.
Tuesday, November 06, 2007
Higher-Performance Computing: Improving the Google File System
For those of you interested in high-performance computing, Doug Judd, our principal search architect at Zvents, has an awesome new post on the Zvents developers blog called "The Google File System - and How It Can Be Improved." Doug is leading our forthcoming Hypertable open-source project, which builds on top of distributed file systems like GFS, HDFS, and Kosmos, and he's got plenty of interesting thoughts on why GFS works well, and where it can be made better.
Subscribe to:
Posts (Atom)